Tens of thousands of Nvidia GPUs sit idle in Meta's Prometheus supercluster, just waiting for a failure
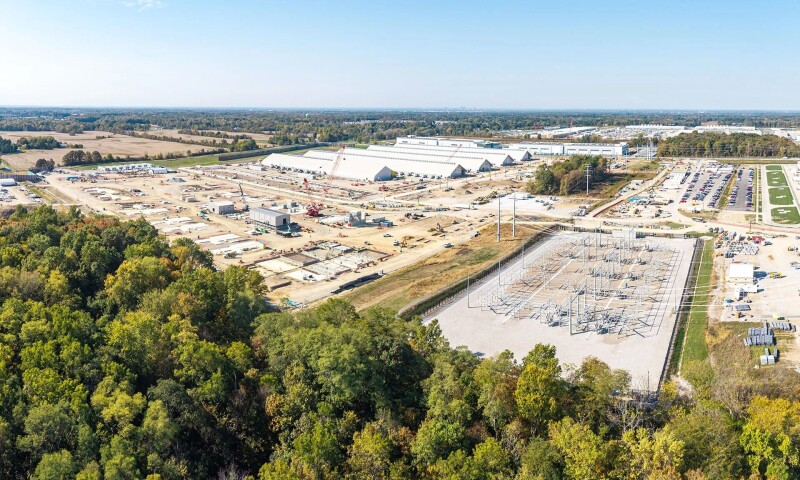
More than 11 percent of the GPUs at Meta’s Prometheus supercluster in New Albany, Ohio, are either dead or sitting idle waiting to step in when the next drops out, Zuckercorp revealed this week.
The massive pool of redundant GPUs is just one of several measures the hyperscaler has taken to keep its AI training runs on track.
Prometheus is among Meta's largest compute deployments to date. Powered by Nvidia's Grace Blackwell and (soon) Vera Rubin rack systems, Meta says the supercluster will eventually scale to a gigawatt of capacity spanning about a million accelerators.
But as anyone who has worked on a large scale compute cluster understands, whether for LLM training or traditional HPC workloads, more chips inevitably means more problems.
In an eight-GPU node, the chance of having a GPU fail is relatively low. In a 100,000-GPU cluster, failures are unavoidable. Meta is building something that's 10x larger and requires distributed training runs across multiple datacenters. …
You're reading a preview. The full article is published by The Register on their website.
Read the full story on The Register