Homelabber’s second-gen Optane build uses two RTX 3090s to run 2.8-trillion-parameter Kimi AI model at 3.11 tokens per second
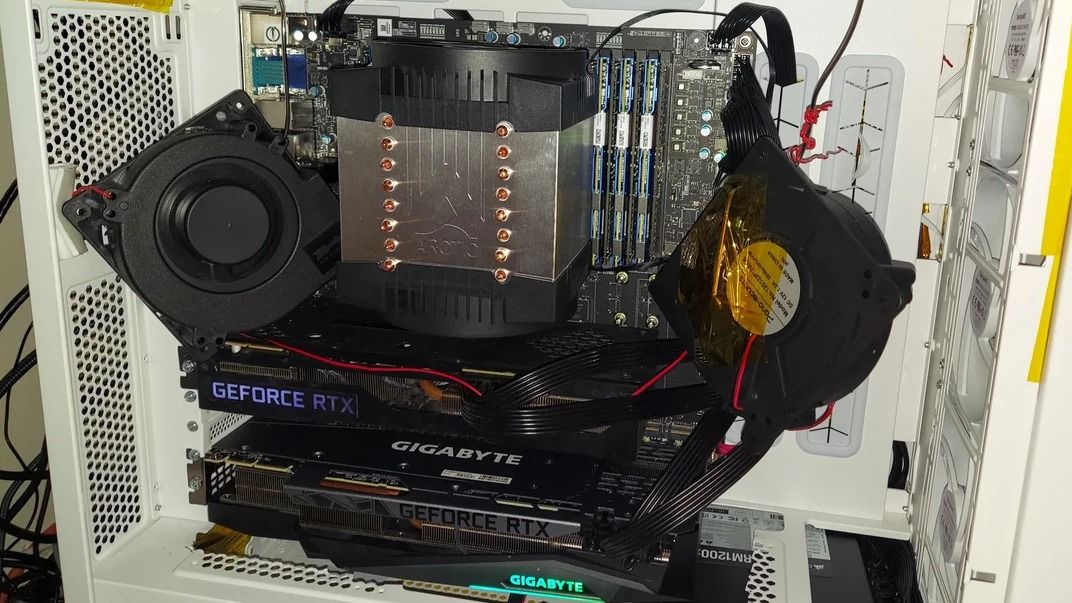
A homelabber detailed improvements to the second-gen Optane AI build in a follow-up post on Reddit, showing the addition of two RTX 3090s to run the 2.8-trillion-parameter Moonshot Kimi K3 model at 3.11 tokens per second. Transferring almost half the model onto a RAM drive added a significant 41% to generation speed and 26% to prompt evaluation. The extra fans are still needed, though, as the persistent Optane memory gets very hot.
That speed is not the most impressive, but it comes with 16.8 tokens per second for prompt evaluation, with 45 of 94 shards, or 414 GB out of 865 GB, living on a RAM drive. Such an arrangement is not new to enthusiasts who would set aside system memory for extra-fast performance in a pseudo-non-volatile manner — it’s still volatile, but appears like a disk — although not everyone has that much RAM sitting around free these days. …
You're reading a preview. The full article is published by Tom's Hardware on their website.
Read the full story on Tom's Hardware