More Performance From Every Byte: How Full-Stack Codesign Solves AI’s Memory Challenge
Larger models, longer contexts and agentic applications are increasing GPU memory pressure while supply tightens and prices rise — a trend expected to continue through the near term.
NVIDIA works closely with memory partners to rapidly adopt the latest memory technologies. NVIDIA was first to adopt HBM3e and HBM4 technologies into an accelerated computing stack.
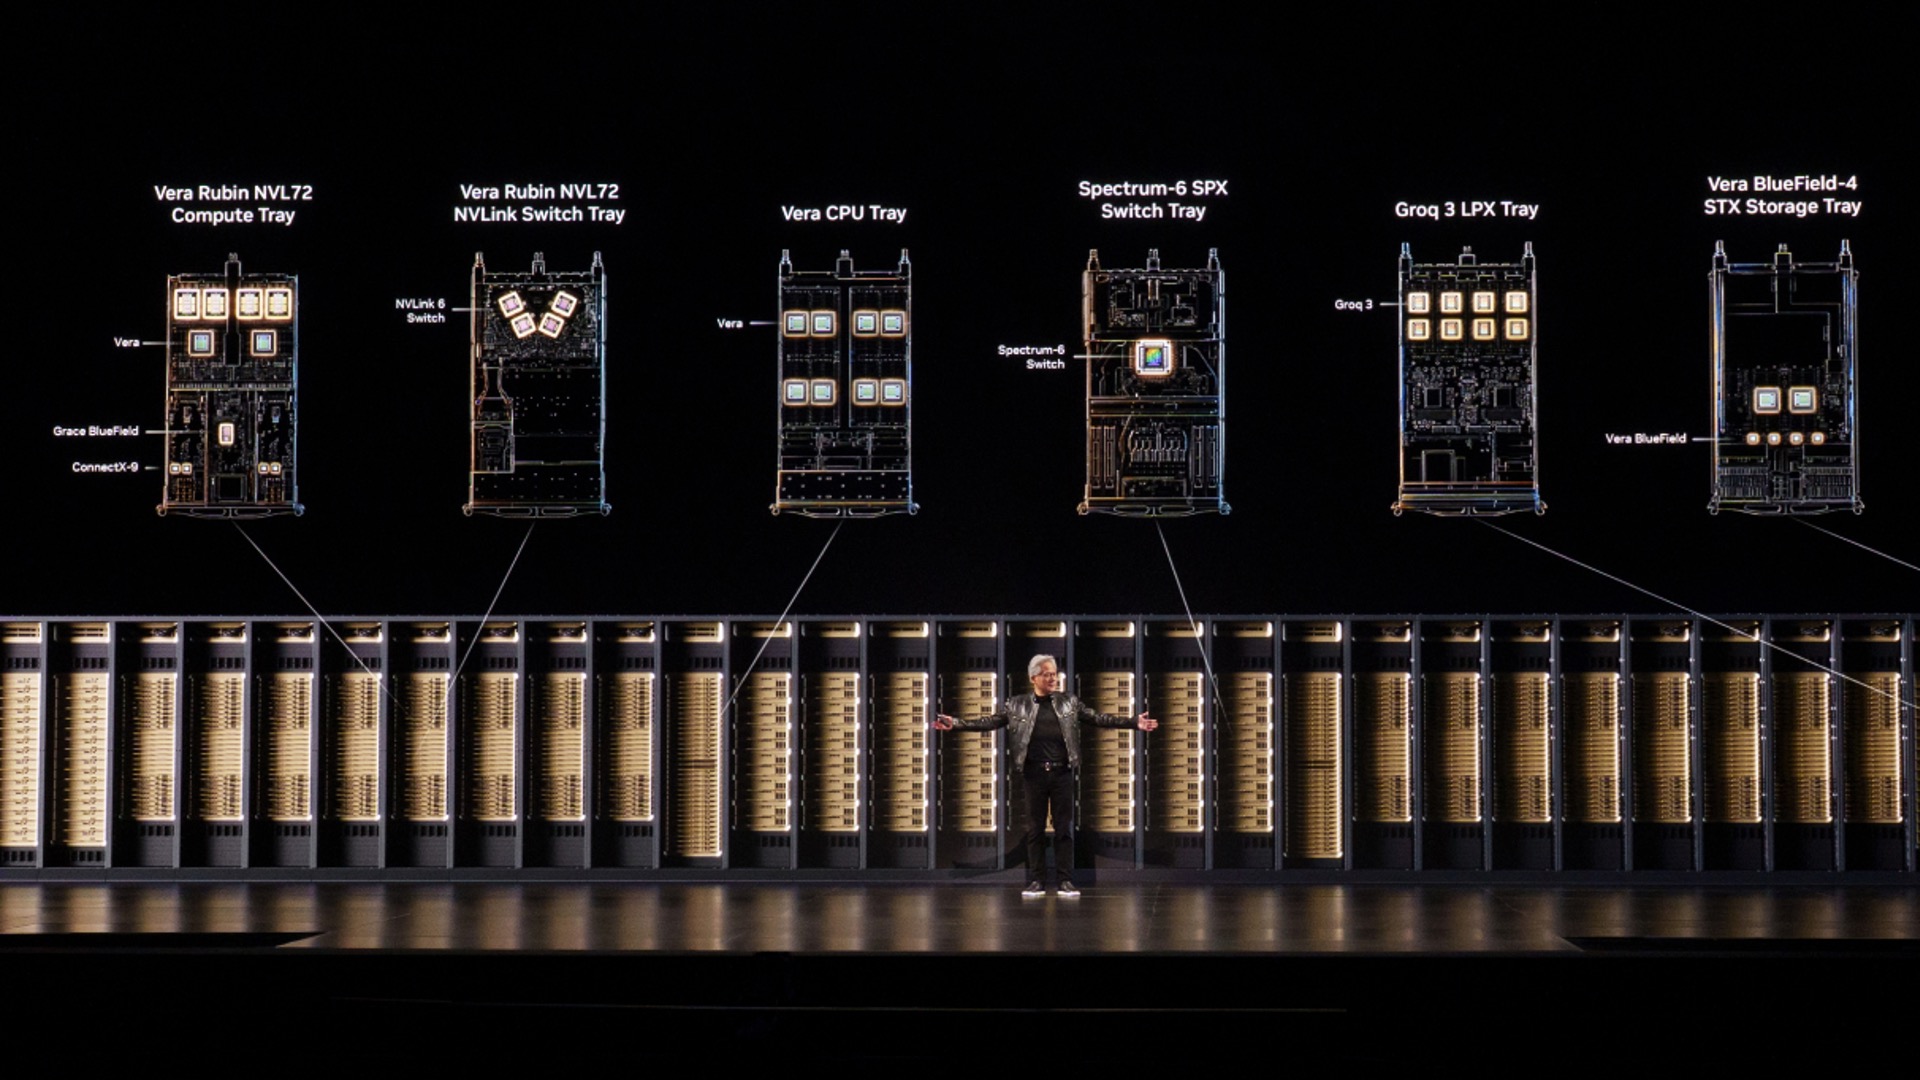
But the approach isn’t to simply pack more memory onto the GPU. It’s full-stack codesign. NVIDIA intentionally designs GPUs, CPUs, networking, storage and software together to get more useful work out of memory at every layer of the AI factory.
That matters because an AI factory runs on a memory and storage hierarchy. GPU high-bandwidth memory (HBM) is the fastest, most expensive and most contested tier — with model weights and KV cache competing for limited capacity. Below it sit CPU memory, local SSDs and shared storage, each trading speed for more capacity at a lower cost per bit.
How much useful work a byte …
You're reading a preview. The full article is published by NVIDIA Blog on their website.
Read the full story on NVIDIA Blog